What is The AI Leaderboard?
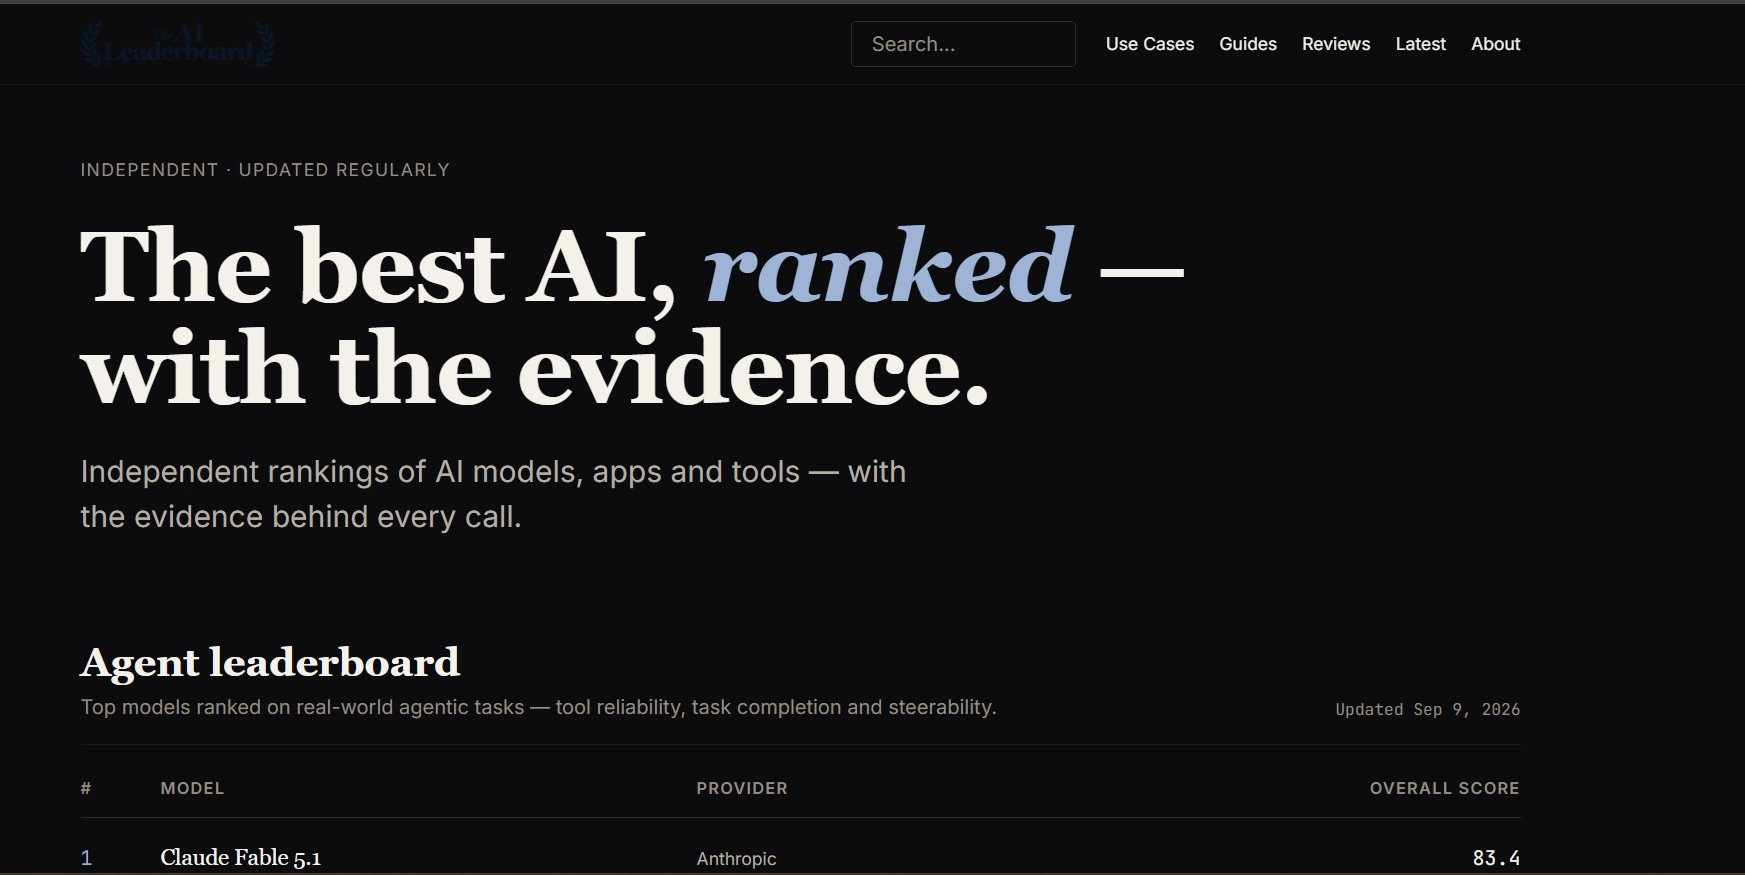
The AI Leaderboard is an independent ranking resource for comparing leading AI models, apps and tools. It positions itself around a simple promise: the best AI, ranked — with the evidence. Rather than relying on a single score or a single opinion, it combines reproducible benchmarks, peer-reviewed studies and independent reviews, and every verdict links back to its supporting evidence.
The rankings cover real-world capability rather than lab demos. Its agent leaderboard, for example, scores models on agentic tasks — tool reliability, task completion and steerability — with entries spanning proprietary and open-weights models from providers such as Anthropic, OpenAI, Meta and Moonshot AI. Alongside the rankings, the platform publishes detailed model guides, provider directories, product reviews, head-to-head comparisons and recommendations for specific use cases.
Who it's for
- Model evaluators and technical buyers — who need current benchmark rankings, pricing, specifications and availability before committing to a model.
- Students and everyday users — looking for practical comparisons of AI study, homework, flashcard and paraphrasing tools.
- Anyone tracking the AI market — who wants a fast daily digest of launches, infrastructure news and policy developments.
Key features
Agent leaderboard
Models are ranked on real-world agentic tasks, covering tool reliability, task completion and steerability. Each entry shows the model, its provider, whether it is proprietary or open weights, and an overall score.
Evidence-linked verdicts
Rankings draw on reproducible benchmarks, peer-reviewed studies and independent reviews rather than a single metric. Every verdict links to the evidence behind it, so claims can be checked rather than taken on trust.
Model guides and comparisons
In-depth guides cover individual models with verified specifications, pricing, access, capabilities, limitations and a practical evaluation framework. Head-to-head comparisons and use-case roundups sit alongside them.
AI Daily Signal
A short daily briefing condenses the last 24 hours in AI into roughly 90 seconds of reading. Recent items have covered new model releases, infrastructure investment and regulatory developments.
What stands out
We test, not guess — and every verdict links to its evidence.
That combination of hands-on testing and traceable sourcing is the core of the proposition. Models run the same controlled trials — agentic tasks, coding, long-context reasoning and tool use — and are re-run when models change, so rankings stay current as new versions ship and benchmarks move. Just as importantly, the platform states that it takes no money from the labs it covers, which matters when rankings influence purchasing and adoption decisions.
Worth checking out if…
You are choosing between AI models and want rankings you can trace back to their sources rather than accept on faith. It is also a sensible stop if you need plain-English guides to specific models, or practical comparisons of AI tools for studying, homework and rewriting. And if keeping up with AI feels like a full-time job, the daily signal offers a quick way to stay current without the noise.